Reinforcement Learning
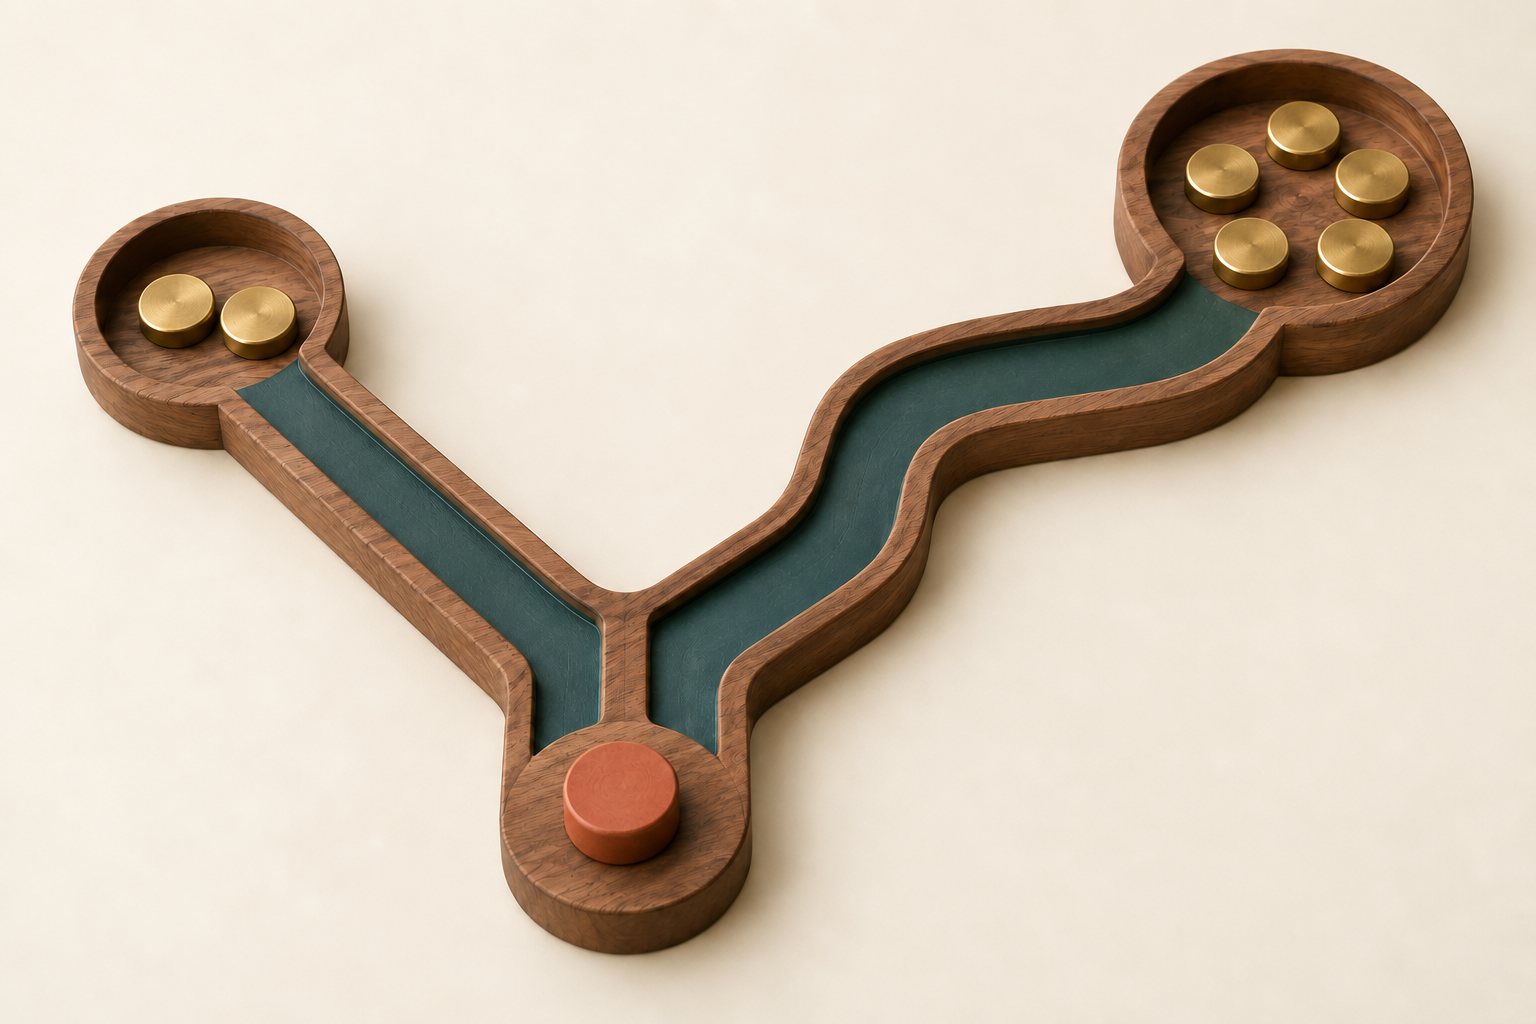
You want to teach a program to win a small game. At a fork, it can choose route A, collect two coins immediately, and finish the second turn without any new coins. Route B gives nothing on the first turn but leads to five coins on the second. The rule “choose what gives the most now” favors A, although B gives the better result after two turns. You also lack a set of ready answers identifying the correct move in every situation. The program can, however, play games and check their results.
Reinforcement Learning (RL) learns a strategy for acting from experience and numerical assessments of actions' consequences. The goal is to increase expected total reward: the result a strategy produces on average across many attempts. A reward need not arrive immediately after a decision. The official Spinning Up, Part 1, “Key Concepts and Terminology”, “Reward and Return”, and “The RL Problem” describes the problem this way.
What the program learns from a game
In our game, the agent is the program choosing a route, and the environment is the game that executes the move and awards coins. The program receives an observation, the available information about the situation, such as its board position. Its policy is its rule for choosing actions; it can also specify probabilities for different moves.
After attempt A, the program records “2, then 0”. Attempt B gives “0, then 5”. The learning algorithm uses this experience to improve the policy, for example choosing B more often at this fork. This describes the goal, rather than one universal update recipe. The result 5 must be connected to the earlier choice of B. If the program always chooses A, it collects no information about B; learning therefore often requires trying less familiar actions too.
The invented game has fixed results and two turns. In a more difficult environment, the same move can have different consequences, so the expected result matters and one success does not prove a good strategy has been found. Simply comparing two known sums is not yet learning either.
In Behavioral cloning, the program learns to imitate actions from examples. In RL, assessments of consequences guide learning. In language models, an action can be generating a response, and a reward can assess its correctness or usefulness. RLHF [Polski] uses information from people for this purpose.
An important boundary: RL improves performance according to the chosen reward. If points reward bypassing rules rather than doing the task, the agent can learn Reward hacking [Polski]. More points need not mean the behavior we actually wanted.
Pick a route, then check the second turn
In this experiment you compare the objective of two strategies; you do not train an agent. Choose a route and reveal the later result. The slider changes the importance of the future reward, rather than the number of coins collected.
We calculate the return, the result for the entire attempt: first reward + γ × second reward. The symbol γ (gamma) weights the future reward. At γ = 1, both turns count fully: A gives 2, B gives 5. At γ = 0.2, we obtain A = 2, B = 1. This is a different evaluation objective for the same game. Boundary values γ = 0 and 1 are allowed here because the attempt ends after two turns; this is not an infinite reward sequence. Formalism source: Spinning Up, “Reward and Return”.
I use AI-generated content as part of my daily learning process.