Overfitting
You run an ice cream stand. For 10 days you wrote down the temperature at noon and the number of scoops sold in a notebook. You want to turn these notes into a rule: tomorrow it will be 24°C, so how much ice cream should you prepare?
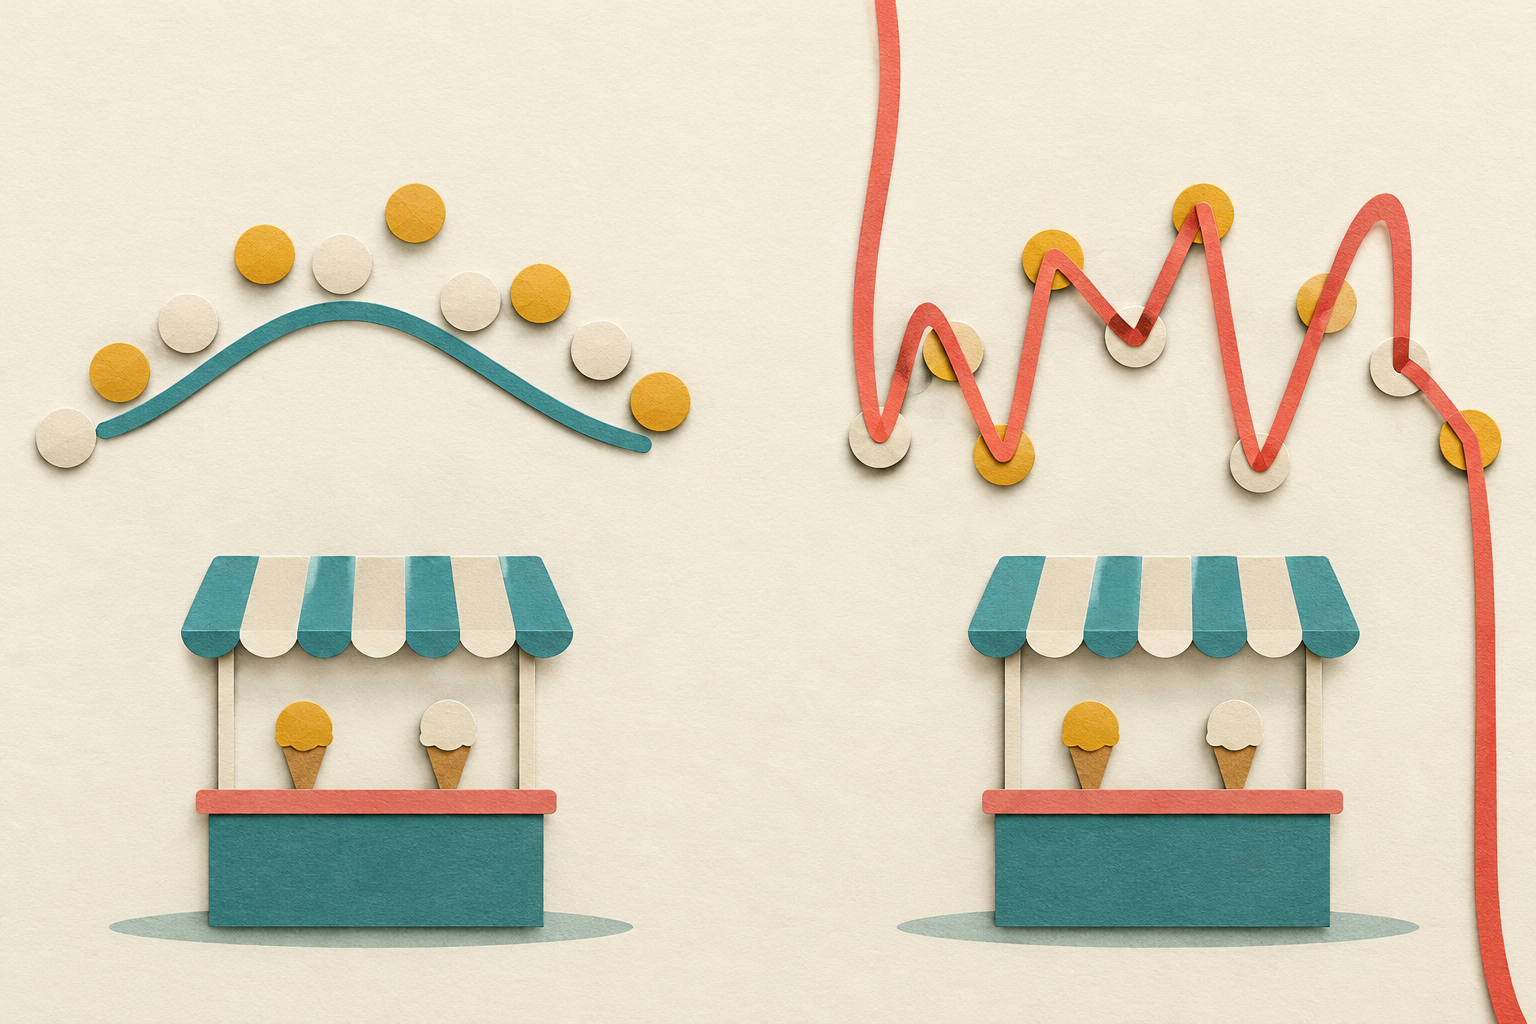
The simplest rule is a straight line: "each extra degree means a few more scoops". In the example from this note, it is typically off by 27.5 scoops on the recorded days, because it does not see that sales drop in the worst heat. So you can give the rule more freedom and let the curve bend. The most flexible of the curves tried here passes exactly through all 10 points. Its error on the days from the notebook is 0.
It looks like a perfect rule. But the days in the notebook are already over, and the rule has to work tomorrow. On 400 new days from the same stand, the "perfect" curve is typically off by 236.5 scoops. A moderately flexible curve, which did worse on the notebook (10.9), is off by 16.8 on the new days.
Overfitting is a situation in which a model has a small error on the data used for learning and, compared with it, too large an error on new data of the same kind (Goodfellow, Bengio and Courville, Deep Learning, §5.2). The model has fitted itself to features of its own data set that do not repeat outside it. The opposite problem is called underfitting: the rule is too simple to describe well even the data it has seen. That is how the straight line in our example behaves.
Where the difference comes from
Every entry in the notebook is made of two things: a pattern (it is warmer, so more ice cream is sold) and chance (a tour group happened to arrive). The rule should capture the first and leave out the second. But the model does not know which is which. It sees only points.
How much chance the model absorbs depends on its flexibility, which the literature calls capacity: the ability to fit many different shapes. The curve in the example is described by 2 to 10 numbers that are chosen to match the data; how many there are is the degree of the curve plus one. A curve of degree 9 has 10 such numbers for 10 days, so it can hit every point, together with all the chance. The authors of the textbook describe it like this: a very flexible model can represent the right relationship, but also a great many others that fit the training data just as well, and there is little chance that it will pick exactly the one that holds up later (§5.2).
The typical course is as follows: as flexibility grows, the error on the training data falls, while the error on new data first falls and then starts to rise (§5.2, figure 5.3). A practical rule follows from this. A model is not judged on the data it learned from, and flexibility is not chosen by the error on that data, because that error will always point to the highest one. Part of the data is set aside: a validation set is used to choose the settings, and a separate test set is used for the final assessment (§5.3).
Try it yourself
Below is the same stand. All the numbers from this note can be reproduced: after clicking "Start over" you see 10 days, and experiments 1–5 set up the cases described.
It is worth doing two things that a static chart does not show. First, turn on "24 other notebooks" and change the degree: at a low degree the gray lines stay close together, at a high degree they spread out in all directions, even though each one comes from the same stand. Second, drag one point high up. The curve of degree 2 will move only a little, while the curve of degree 9 will reshape itself along its whole length to hit it.
What helps
- More data. With 80 days, the same curve of degree 9 is typically off by 14.8 scoops on the notebook and by 15.9 on new days. The difference almost disappears, because the curve can no longer hit every point (§5.2).
- Less flexibility. A curve of degree 3 on 10 days: 10.9 on the notebook, 16.8 on new days.
- Regularization, that is, a change to the way of learning that is meant to reduce the error on new data, not on the training data (§5.2.2). One example is a penalty for large coefficients, related to Weight decay: a curve of degree 9 with a penalty of λ = 0.01 is off by 5.8 on the notebook and by 21.2 on new days, instead of by 236.5.
None of these settings can be chosen by looking only at the error on the training data.
Limitations
- This is my own example with a single input quantity and simulated data. Chance alone gives a typical error of 15 scoops here, and no rule will go lower on new days.
- The "first better, then worse" shape is typical, not guaranteed. The authors note that in deep networks it is hard even to determine the model's actual flexibility, because it also depends on the learning algorithm (§5.2). So the number of parameters of an LLM does not tell you by itself whether the model is overfitted.
- A small error on new data applies to data from the same source. If the stand moves to the seaside, the notebook from the city promises nothing.
Related notes
- Weight decay limits the size of the weights and is one of the ways to reduce the difference between the error on training data and on new data.
- Grokking describes cases in which a model that looks overfitted starts to work well on new data after long further training.
- Fine-tuning on a small data set needs the same check: separate data that the model did not see while learning.
- Catastrophic Forgetting [Polski] is a different problem: there the model loses an old skill after new learning, while here it carries over poorly beyond its own training data from the start.