Glossary term · · 3 min read
Fisher Information
You want to find out whether a bag of coffee weighs closer to 100 or 101 g. You place it on two scales. Both are calibrated, but on one the readings barely budge, while on the other they jump by several grams. A reading of 101 g on the second scale settles little: that number would not be surprising even if the bag weighed 100 g. How many repeats would make up for that scatter?
Fisher Information measures how strongly the predicted chances of different observations change when you nudge the unknown number, or parameter. Here the parameter is the mass of the coffee. If two nearby guesses about the mass lead to almost the same predictions, a reading does little to tell them apart. On the steadier scale, readings cluster closer to the true mass, so shifting that mass by a gram changes the predictions more clearly.
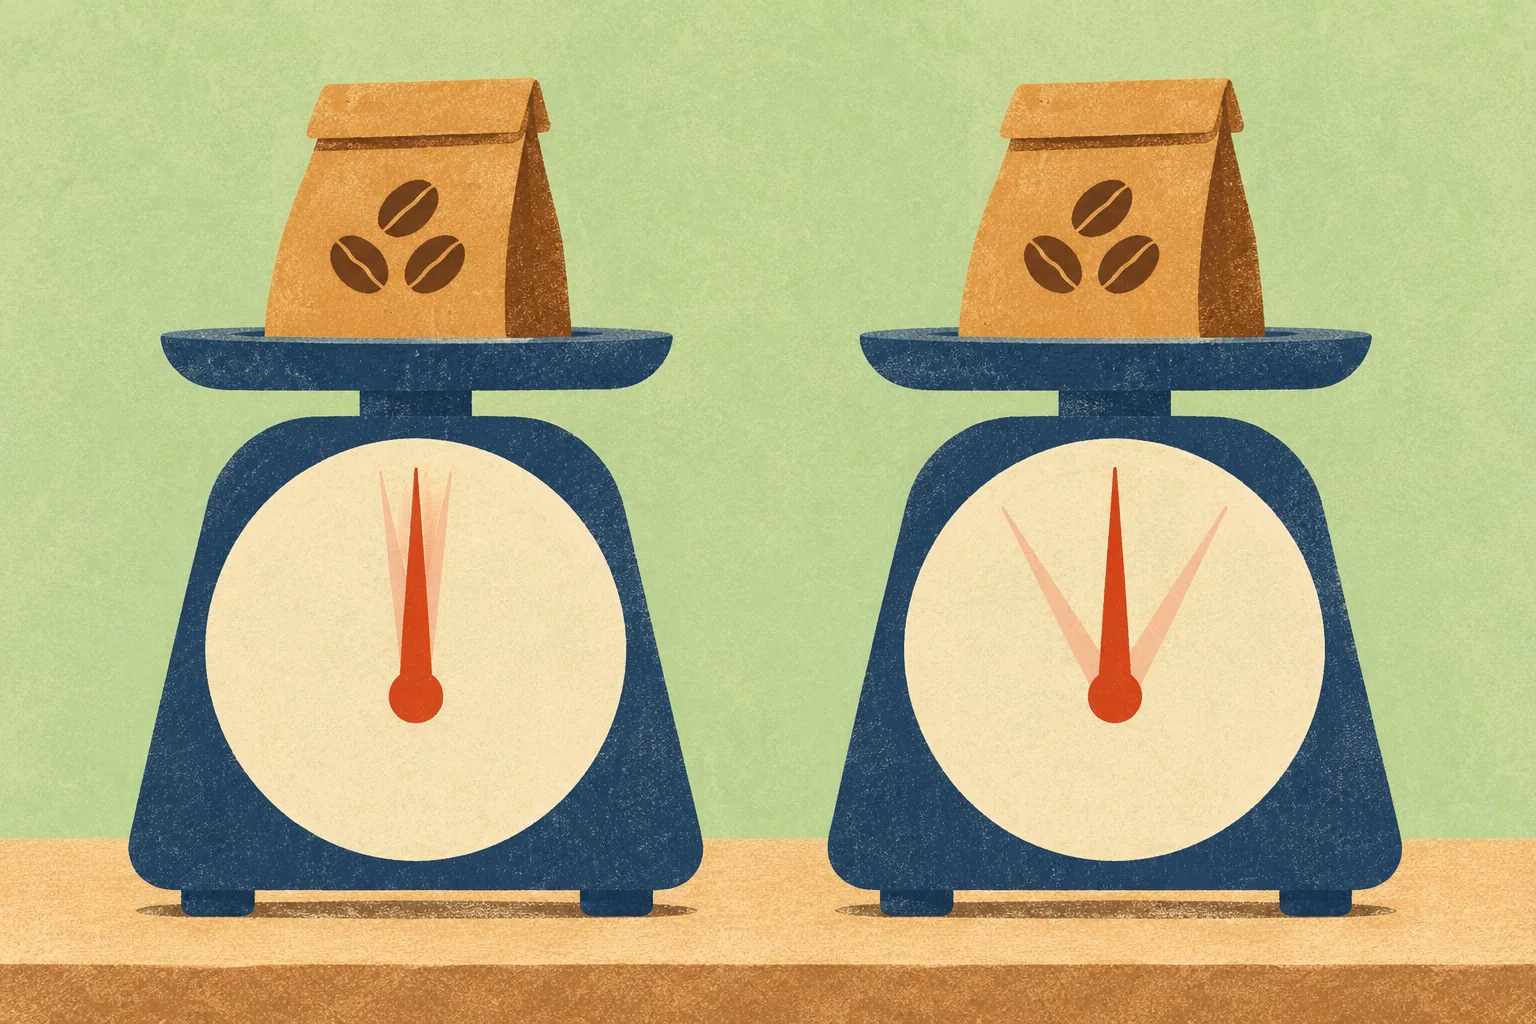
Four weighings instead of one?
Let's simplify: errors are random, form a symmetric bell around zero, and do not depend on previous readings. Their spread is described by the standard deviation: 1 g on the steadier scale and 2 g on the other. In this model, the information about mass in one reading is 1 divided by the square of that deviation. The steadier scale gives 1 and the other ¼, both in units of 1/g². The figures add up for independent readings: four weighings on the second scale give as much information as one on the steadier scale (DasGupta, Classic Theory of Point Estimation, §§6.2.4–6.2.5 and Example 6.13).
Change the number of readings on the less steady scale. When does their average have the same spread as a single reading on the steadier scale? The demo calculates the information and the spread of the average: the standard deviation of one reading divided by the square root of the number of weighings.
If a scale always adds 1 g, the average of many weighings will still be biased by 1 g. More information in this model helps limit the effect of random scatter; it does not detect poor calibration.
What does that tell us about a language model?
Instead of the mass, take one model weight, a number used in its calculations. An observation could be a selected piece of text. Now ask whether nudging that weight clearly changes the chances of the different answers. KL Divergence compares the whole sets of chances; Fisher Information describes how much that comparison grows for a small change in the parameter (Pascanu and Bengio, §2, Equation 4). With many weights, the full matrix, a table of numbers, also accounts for changes to weights together. Elastic Weight Consolidation uses only the diagonal of that table: it puts stronger brakes on changes to weights that the earlier task is more sensitive to (Kirkpatrick et al., §2).
AI helped prepare the text and illustration. The weighings are a hypothetical example.